Key Summary
Retrieval-Augmented Generation, commonly known as RAG, is an AI architecture that allows a generative AI model to retrieve relevant information from an external knowledge source before generating a response.
Large language models can produce fluent answers, but their built-in knowledge may not contain an organization’s private documents, recently updated information, internal policies, or specialized domain knowledge. RAG addresses this limitation by connecting the model to an external information source.
Instead of asking an LLM to answer entirely from its learned parameters, a RAG system retrieves relevant information and provides it as context for generation.
This makes RAG particularly useful for enterprise search, customer support, research, document analysis, internal knowledge assistants, and other applications where answers need to be grounded in specific information.
What is retrieval augmented generation (RAG)?
Retrieval-Augmented Generation is a technique that combines a retrieval system with a generative AI model. A conventional LLM generates an answer based primarily on patterns and information learned during training. A RAG system introduces an additional information retrieval step. Suppose a company has thousands of internal documents:
documents = [
“employee_handbook.pdf”,
“security_policy.pdf”,
“leave_policy.pdf”,
“expense_policy.pdf”
]
These documents can be processed and indexed. When someone asks:
How many days of parental leave are available?
The RAG system searches the company’s knowledge base for relevant content. The retrieved content is then supplied to the LLM as context. A simplified version of the concept can be represented in Python as:
question = “How many days of parental leave are available?”
context = retrieve_relevant_documents(question)
prompt = f”””
Answer the question using the provided context.
Context:
{context}
Question:
{question}
“””
answer = language_model.generate(prompt)
print(answer)
The important distinction is that the language model is not expected to independently know the organization’s latest policy. It receives relevant information at inference time.
How does Retrieval-Augmented Generation work?
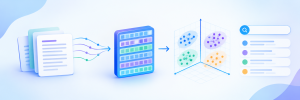
A RAG system generally involves four major stages: creating external data, retrieving relevant information, augmenting the prompt, and keeping the external knowledge current.
1. Create external data
The first step is to identify the information the AI application should be able to access.
This could include:
- PDF documents
- Websites
- Product manuals
- Internal policies
- Customer records
- Knowledge bases
- Research papers
- Databases
- Support tickets
- Technical documentation
Large documents are usually divided into smaller chunks before being indexed.
For example:
document = “””
Retrieval-Augmented Generation combines information retrieval
with language model generation. It allows an AI system to
retrieve external information before generating an answer.
“””
chunk_size = 100
chunks = [
document[i:i + chunk_size]
for i in range(0, len(document), chunk_size)
]
print(chunks)
Real RAG applications use more sophisticated chunking strategies that consider sentences, paragraphs, token limits, and document structure. After chunking, each piece of content can be converted into an embedding.
from sentence_transformers import SentenceTransformer
model = SentenceTransformer(“all-MiniLM-L6-v2”)
embeddings = model.encode(chunks)
print(embeddings.shape)
The embeddings can then be stored in a vector database.
2. Retrieve relevant information
When a user submits a question, the question is converted into an embedding using the same or a compatible embedding model.
query = “How does RAG retrieve information?”
query_embedding = model.encode([query])
print(query_embedding.shape)
The system then compares the query embedding with stored document embeddings. A simplified similarity search could look like this:
from sklearn.metrics.pairwise import cosine_similarity
scores = cosine_similarity(
query_embedding,
embeddings
)[0]
best_index = scores.argmax()
print(chunks[best_index])
Production systems generally use vector indexes or dedicated vector databases rather than calculating similarity against every document manually.
3. Augment the LLM prompt
After retrieving relevant chunks, the application adds them to the prompt.
context = chunks[best_index]
prompt = f”””
Use the following context to answer the question.
Context:
{context}
Question:
{query}
Answer:
“””
The language model can now generate an answer based on the retrieved information.
This is the “augmentation” part of Retrieval-Augmented Generation.
4. Update external data
One of the major advantages of RAG is that the external knowledge source can be updated independently of the language model. Suppose a company changes its leave policy. The organization does not necessarily need to retrain its entire language model. Instead, the updated document can be processed, embedded, and added to the knowledge base.
A simplified update process might look like:
new_document = load_document(“updated_leave_policy.pdf”)
new_chunks = split_into_chunks(new_document)
new_embeddings = model.encode(new_chunks)
vector_database.upsert(
documents=new_chunks,
embeddings=new_embeddings
)
This makes RAG practical for information that changes frequently.
What are the Components of a RAG system?
A RAG architecture normally contains four major components.
1. The knowledge base
The knowledge base contains the information that the system can retrieve.
It may consist of structured or unstructured data.
Examples include:
- Company documents
- Product documentation
- Databases
- Research papers
- Websites
- FAQs
- Customer support records
The quality of the knowledge base directly affects the quality of retrieval.
2. The retriever
The retriever searches the knowledge base for information relevant to the user’s query. Vector search is a common approach, but RAG systems can also use keyword search, metadata filtering, hybrid search, or more advanced retrieval techniques. A simple semantic retriever could be implemented as:
def retrieve(query, documents, document_embeddings, model, top_k=3):
query_embedding = model.encode([query])
scores = cosine_similarity(
query_embedding,
document_embeddings
)[0]
top_indices = scores.argsort()[-top_k:][::-1]
return [documents[i] for i in top_indices]
The top_k value determines how many relevant chunks are returned.
3. The integration layer
The integration layer connects retrieval with generation.
It handles tasks such as:
- Query processing
- Retrieval
- Context construction
- Prompt creation
- Model invocation
- Response handling
For example:
def build_prompt(question, context):
return f”””
Answer the question using only the supplied context.
Context:
{context}
Question:
{question}
Answer:
“””
This layer is also where developers can implement access controls, metadata filtering, citations, logging, and other application-specific logic.
4. The generator
The generator is the language model responsible for producing the final response. The generator receives the user’s question along with the retrieved context. A simplified application could look like:
documents = retrieve(
query,
chunks,
embeddings,
model,
top_k=3
)
context = “\n\n”.join(documents)
prompt = build_prompt(query, context)
response = llm.generate(prompt)
print(response)
In a production system, the generator could be an API-based LLM or a locally deployed language model.
What are the benefits of RAG?
1. Cost-efficient AI implementation and AI scaling
RAG can reduce the need to repeatedly retrain or fine-tune a model whenever external information changes. The knowledge layer can be updated independently, which can make maintaining domain-specific AI applications more practical.
2. Access to current and domain-specific data
RAG allows an AI application to access information that may not have been included in the original training data. This is particularly useful for:
- Internal company information
- Current documentation
- Product information
- Regulatory material
- Technical manuals
- Frequently changing policies
3. Lower risk of AI hallucinations
RAG can reduce the likelihood of unsupported responses by providing relevant source material to the language model. However, retrieval does not automatically eliminate hallucinations. Poor retrieval, incomplete documents, ambiguous questions, or incorrect generation can still produce inaccurate answers.
A well-designed system should therefore evaluate both retrieval quality and generation quality.
4. Increased user trust
When an AI application can identify the documents or passages used to answer a question, users can have greater visibility into where the response originated. For example, a system can return an answer along with source metadata:
result = {
“answer”: response,
“sources”: [
{
“document”: “employee_handbook.pdf”,
“page”: 42
}
]
}
print(result)
5. Expanded use cases
RAG can connect generative AI to specialized knowledge without requiring the model itself to contain all that information.
This enables applications such as technical support assistants, internal knowledge systems, research assistants, and document question-answering tools.
6. Enhanced developer control and model maintenance
Developers can independently manage the knowledge layer.
They can control:
- Which documents are indexed
- Which users can access particular data
- How documents are chunked
- How retrieval works
- Which sources are returned
- How prompts are constructed
7. Greater data security
A RAG system can be designed around controlled access to an organization’s own data.
For example, metadata can be used to restrict retrieval:
results = vector_database.search(
query_embedding,
filters={
“department”: “finance”,
“access_level”: “internal”
}
)
This allows retrieval to consider permissions instead of treating the entire knowledge base as universally accessible.
What are the different RAG use cases?
1. Specialized chatbots and virtual assistants
Organizations can build assistants that answer questions using internal or domain-specific information. For example, an HR assistant could retrieve information from employee policies instead of relying on general-purpose model knowledge.
2. Research
Researchers can use RAG systems to retrieve relevant papers, reports, and documents before generating summaries or answers. This is especially useful when the information source is large and manually searching every document would be inefficient.
3. Content generation
RAG can provide factual context for content generation. For example, a marketing system could retrieve product specifications before generating product descriptions.
4. Market analysis and product development
Companies can retrieve information from customer feedback, market reports, product documentation, and support tickets to help identify trends and opportunities.
5. Knowledge engines
Organizations can build systems that make large internal knowledge repositories easier to query.
Instead of searching through folders manually, users can ask natural-language questions.
6. Recommendation services
RAG can retrieve relevant products, documents, articles, or other content based on a user’s query or profile.
7. Enterprise AI applications
RAG provides a practical way to connect generative AI models to enterprise information while maintaining greater control over what information is retrieved and supplied to the model.
Why is Retrieval-Augmented Generation important?
RAG is important because modern AI applications increasingly need access to information beyond the model’s original training data. A general-purpose LLM may be capable of explaining a concept such as employee leave policies, but it cannot automatically know the latest policy document of a particular organization.
RAG creates a connection between generative AI and external knowledge. It also separates two responsibilities:
- The retrieval system determines what information is relevant.
- The language model determines how to use that information to generate a response.
This separation allows developers to update knowledge without necessarily changing the underlying language model. RAG is therefore particularly useful when information is private, specialized, frequently updated, or too large to include directly in every prompt.
What is the difference between RAG and fine-tuning?
RAG and fine-tuning solve different problems. Fine-tuning changes a model’s behavior by training it further on a specific dataset. It can be useful when developers want the model to follow a particular style, format, or task behavior. RAG does not fundamentally change the model’s learned parameters. Instead, it provides external information at inference time. Consider an organization’s internal documentation.
With RAG, the documents can remain in an external knowledge base. When a question is asked, relevant sections are retrieved and supplied to the model. With fine-tuning, the organization would train the model further using a prepared dataset. RAG is generally more suitable when the primary requirement is access to changing or private information. Fine-tuning can be useful when the primary requirement is changing model behavior or adapting the model to a specialized task. The two approaches can also be combined. A system might use a fine-tuned model for a particular interaction style while using RAG to provide current domain-specific information.
What are the RAG Alternatives?
RAG is not the only way to provide an AI system with additional information.
- Fine-tuning can adapt a model to specific behaviors, formats, or tasks.
- Long-context prompting can provide large amounts of information directly within the model’s context window, although this can increase token usage and may not be practical for very large knowledge bases.
- Traditional search can retrieve documents or web pages using keyword-based techniques without requiring an LLM to generate the final answer.
- Knowledge graphs can represent entities and relationships explicitly and can be useful when applications require structured reasoning over connected information.
- Tool-augmented systems can allow an AI model to query APIs, databases, calculators, or other external services instead of relying solely on retrieved documents.
In practice, modern AI systems may combine several of these approaches.
What is the difference between Retrieval-Augmented Generation and semantic search?
Semantic search and RAG are closely related but perform different roles. Semantic search focuses primarily on retrieving information based on meaning. For example, a user might search:
How can I reset my company laptop password?
A semantic search system can retrieve a document titled:
Corporate Device Credential Recovery Procedure
even though the exact phrase “reset my company laptop password” does not appear in the document title.
RAG uses retrieval as one part of a larger generation pipeline. The retrieved information is passed to a language model, which generates a response based on that context. Therefore, semantic search can exist independently, while RAG typically uses retrieval as an input to generative AI. A simplified semantic search implementation might look like:
query_embedding = model.encode(
[“How can I reset my password?”]
)
results = vector_database.search(
query_embedding,
top_k=5
)
for result in results:
print(result)
A RAG system would continue beyond retrieval by constructing a prompt and asking an LLM to generate an answer using the retrieved results.
Conclusion
Retrieval-Augmented Generation provides a practical architecture for connecting generative AI with external knowledge. Instead of relying entirely on information learned during model training, a RAG system retrieves relevant information and supplies it to the language model when a response is generated.
This makes RAG particularly useful for applications that depend on private, specialized, or frequently changing information. It can support enterprise assistants, research tools, customer support systems, knowledge engines, recommendation applications, and many other AI workflows.
For AI and machine learning professionals, understanding RAG also provides a foundation for working with vector embeddings, vector databases, semantic search, prompt engineering, and modern LLM applications.
Frequently Asked Questions (FAQs)
1. What is Retrieval-Augmented Generation (RAG)?
Retrieval-Augmented Generation is an AI architecture that combines information retrieval with generative AI. It retrieves relevant information from an external knowledge source and provides that information to a language model as context for generating a response.
2. How does Retrieval-Augmented Generation work?
A RAG system processes and stores external information, retrieves relevant content when a user submits a query, adds that content to the model’s context, and then uses a language model to generate a response based on the retrieved information.
3. What are the benefits of using RAG in AI?
RAG can provide access to current and domain-specific information, reduce the need to retrain models when external information changes, improve control over the knowledge used by an AI application, and support use cases involving private or specialized data.
4. What are the main components of a RAG system?
The main components are a knowledge base containing external information, a retriever that finds relevant content, an integration layer that manages retrieval and prompt construction, and a generator that produces the final response.
5. What is the difference between RAG and fine-tuning?
RAG provides external information to a model at inference time, while fine-tuning further trains the model on specialized data to modify its behavior or capabilities. RAG is particularly useful for changing or private knowledge, while fine-tuning is often used for adapting model behavior to specific tasks or formats.