Key Summary
Training a neural network involves teaching a machine learning model to identify patterns in data and use those patterns to make predictions. The process typically includes preparing a dataset, selecting an architecture, initializing the model, calculating predictions, measuring errors, updating model weights, and evaluating performance on unseen data.
The basic idea sounds straightforward, but successful neural network training depends on several interconnected decisions. The quality of the training data, choice of architecture, loss function, optimizer, learning rate, batch size, and number of training iterations can all affect the final model.
Whether you are learning how to train a neural network for classification, regression, computer vision, or another AI application, understanding the training process is essential.
What is a neural network?
A neural network is a machine learning model inspired loosely by the structure of biological neural systems. It consists of interconnected computational units called neurons, organized into layers. Each neuron receives inputs, applies weights, adds a bias, and passes the result through an activation function. A simplified neuron can be represented in Python as:
import numpy as np
inputs = np.array([0.5, 0.8, 0.2])
weights = np.array([0.4, 0.7, 0.3])
bias = 0.1
weighted_sum = np.dot(inputs, weights) + bias
print(weighted_sum)
The neural network learns by adjusting the weights and biases so that its predictions become increasingly accurate. For example, a neural network trained to classify images of cats and dogs receives image data as input and gradually learns patterns that help distinguish the two categories.
How do neural networks work?
A neural network processes information through multiple layers. Consider a simple network receiving three input values:
x = np.array([0.2, 0.5, 0.9])
The first layer transforms the input using weights and biases:
weights = np.array([
[0.2, 0.4],
[0.7, 0.1],
[0.5, 0.3]
])
bias = np.array([0.1, 0.2])
z = np.dot(x, weights) + bias
print(z)
An activation function then introduces non-linearity.
A commonly used activation function is ReLU:
def relu(x):
return np.maximum(0, x)
activated = relu(z)
print(activated)
Multiple layers can be connected to create a deeper network.
During training, the model compares its prediction with the correct answer and uses the resulting error to adjust its parameters.
What is the Importance of Neural Networks?
Neural networks are important because they can learn complex relationships from large datasets without requiring every relevant feature to be manually programmed.
They are widely used in:
- Image recognition
- Natural language processing
- Speech recognition
- Recommendation systems
- Fraud detection
- Time-series forecasting
- Medical image analysis
- Autonomous systems
- Generative AI
For example, traditional image classification systems may require manually engineered features. A convolutional neural network can instead learn useful visual representations directly from training images.
Neural networks are also highly flexible. By changing the architecture and training process, the same general concept can be applied to very different problems.
What are the different Layers in Neural Network Architecture?
Neural networks can contain several types of layers.
1. Input layer
The input layer receives the features provided to the model. For a tabular dataset containing ten numerical features, the input layer would accept ten values for each example.
2. Hidden layers
Hidden layers transform the information received from previous layers. A network can contain one hidden layer or many.
from tensorflow.keras import Sequential
from tensorflow.keras.layers import Dense
model = Sequential([
Dense(64, activation=”relu”, input_shape=(10,)),
Dense(32, activation=”relu”)
])
Here, the network contains two hidden layers with 64 and 32 neurons.
Output layer
The output layer produces the final prediction. For binary classification, a single neuron with a sigmoid activation is common:
model = Sequential([
Dense(64, activation=”relu”, input_shape=(10,)),
Dense(32, activation=”relu”),
Dense(1, activation=”sigmoid”)
])
For multi-class classification with five classes, the output layer could contain five neurons with a softmax activation:
model = Sequential([
Dense(64, activation=”relu”, input_shape=(10,)),
Dense(32, activation=”relu”),
Dense(5, activation=”softmax”)
])
What are the types of Neural Networks?
Different neural network architectures are designed for different types of data and tasks.
- Feedforward neural networks process information from the input toward the output without recurrent connections. They are commonly used for tabular classification and regression.
- Convolutional neural networks (CNNs) are designed to process spatial information and are widely used for image and computer vision tasks.
- Recurrent neural networks (RNNs) were designed for sequential data and can maintain information across sequence steps.
- Long Short-Term Memory networks (LSTMs) are a type of recurrent architecture designed to handle longer-term dependencies in sequences.
- Transformers use attention mechanisms to process relationships between elements in a sequence and are widely used in modern NLP and generative AI.
The appropriate architecture depends on the characteristics of the problem and dataset.
How does Neural Networks work?
Neural network training involves repeatedly processing data, measuring the error, and adjusting model parameters.
1. Forward Propagation
During forward propagation, input data passes through the network to produce a prediction.
For example:
import tensorflow as tf
x = tf.constant([[0.2, 0.5, 0.9]])
layer = tf.keras.layers.Dense(
2,
activation=”relu”
)
output = layer(x)
print(output)
The network performs mathematical operations at each layer until it produces an output.
2. Backpropagation
The model then calculates how far its prediction is from the expected output. A loss function measures this difference. For binary classification:
loss_function = tf.keras.losses.BinaryCrossentropy()
y_true = tf.constant([[1.0]])
y_pred = tf.constant([[0.7]])
loss = loss_function(y_true, y_pred)
print(loss.numpy())
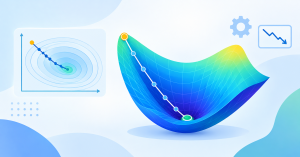
Backpropagation calculates gradients showing how changes to each parameter would affect the loss.
An optimizer uses these gradients to update the model’s weights.
3. Iteration
The process is repeated across batches of training data.
A complete pass through the training dataset is called an epoch.
For example:
model.fit(
x_train,
y_train,
epochs=20,
batch_size=32
)
With 20 epochs, the model processes the training dataset repeatedly, updating its parameters after each batch.
The objective is to reduce the loss while maintaining good performance on unseen data.
Learning of a Neural Network
Neural networks can learn using different machine learning paradigms.
1. Learning with Supervised Learning
In supervised learning, the training dataset contains input data and corresponding target labels.
For example:
x_train = [
[25, 50000],
[35, 70000],
[45, 90000]
]
y_train = [0, 1, 1]
The model learns a relationship between the input features and target values. Supervised learning is commonly used for classification and regression.
2. Learning with Unsupervised Learning
Unsupervised learning uses data without predefined target labels. A neural network can learn useful representations or identify patterns in the data. Autoencoders are one example:
from tensorflow.keras import Sequential
from tensorflow.keras.layers import Dense
autoencoder = Sequential([
Dense(16, activation=”relu”, input_shape=(32,)),
Dense(8, activation=”relu”),
Dense(16, activation=”relu”),
Dense(32, activation=”sigmoid”)
])
The network can learn a compressed representation of the input and reconstruct it.
3. Learning with Reinforcement Learning
Reinforcement learning involves an agent interacting with an environment. The agent receives rewards or penalties based on its actions and learns a strategy for maximizing future rewards. Neural networks can act as function approximators in reinforcement learning algorithms. For example, a neural network could estimate the value of possible actions in a game.
How to implement a Neural Network using TensorFlow?
TensorFlow provides high-level APIs that make it possible to build and train neural networks without implementing every mathematical operation manually.
Step 1: Import Necessary Libraries
Start by importing TensorFlow and the required components.
import tensorflow as tf
from tensorflow.keras.models import Sequential
from tensorflow.keras.layers import Dense
You can also use NumPy to prepare numerical data:
import numpy as np
Step 2: Create and Load Dataset
For demonstration, we can create a small binary classification dataset.
x_train = np.array([
[1.0, 2.0],
[1.5, 2.5],
[3.0, 4.0],
[3.5, 4.5],
[5.0, 6.0],
[5.5, 6.5]
])
y_train = np.array([
0,
0,
1,
1,
1,
1
])
For a real machine learning project, the dataset would typically be loaded from a file, database, or data pipeline.
It is also important to separate training and test data:
from sklearn.model_selection import train_test_split
x_train, x_test, y_train, y_test = train_test_split(
x_train,
y_train,
test_size=0.2,
random_state=42
)
Feature scaling can also improve training:
from sklearn.preprocessing import StandardScaler
scaler = StandardScaler()
x_train = scaler.fit_transform(x_train)
x_test = scaler.transform(x_test)
Notice that the scaler is fitted only on the training data. The same transformation is then applied to the test data.
Step 3: Create a Neural Network
Now create the model architecture.
model = Sequential([
Dense(16, activation=”relu”, input_shape=(2,)),
Dense(8, activation=”relu”),
Dense(1, activation=”sigmoid”)
])
The first layer accepts two input features.
The hidden layers use ReLU activation, while the final layer uses sigmoid because this example is a binary classification problem. You can inspect the architecture with:
model.summary()
Step 4: Compiling the Model
Before training, configure the loss function, optimizer, and evaluation metrics.
model.compile(
optimizer=”adam”,
loss=”binary_crossentropy”,
metrics=[“accuracy”]
)
The optimizer determines how the model’s parameters are updated.
Adam is widely used because it adapts the learning process based on gradient information.
Step 5: Train the Model
The model can now be trained:
history = model.fit(
x_train,
y_train,
epochs=50,
batch_size=2,
validation_split=0.2,
verbose=1
)
The history object stores information about the training process.
You can inspect the loss values:
print(history.history[“loss”])
print(history.history[“val_loss”])
Monitoring validation loss is important because a model can perform increasingly well on its training data while becoming worse at generalizing to unseen examples.
Early stopping can help prevent unnecessary training:
from tensorflow.keras.callbacks import EarlyStopping
early_stopping = EarlyStopping(
monitor=”val_loss”,
patience=5,
restore_best_weights=True
)
history = model.fit(
x_train,
y_train,
epochs=100,
validation_split=0.2,
callbacks=[early_stopping]
)
Step 6: Make Predictions
Once training is complete, the model can generate predictions for new data.
predictions = model.predict(x_test)
print(predictions)
For binary classification, the model outputs probabilities between 0 and 1.
These probabilities can be converted into class labels:
predicted_classes = (predictions >= 0.5).astype(int)
print(predicted_classes)
The model can then be evaluated against the test labels:
test_loss, test_accuracy = model.evaluate(
x_test,
y_test,
verbose=0
)
print(“Test accuracy:”, test_accuracy)
For a real project, accuracy should not always be the only metric. Depending on the task, precision, recall, F1 score, mean squared error, or other metrics may be more appropriate.
Conclusion
Training a neural network is an iterative process in which a model learns patterns from data by repeatedly making predictions, measuring errors, calculating gradients, and updating its parameters.
The overall workflow begins with preparing suitable training data and selecting an appropriate architecture. The model is then trained using forward propagation and backpropagation, while an optimizer adjusts its weights. Validation and test data help determine whether the model is learning patterns that generalize beyond the examples it saw during training.
The most effective neural network training process is not simply about increasing the number of layers or training for more epochs. Data quality, architecture, preprocessing, optimization, regularization, and evaluation all contribute to the final result.
For anyone learning artificial intelligence or machine learning, understanding this training cycle provides the foundation for working with more advanced architectures such as convolutional neural networks, recurrent networks, transformers, and large-scale deep learning systems.
Frequently Asked Questions (FAQs)
1. How do you train a neural network?
You train a neural network by providing it with training data, selecting an appropriate architecture and loss function, generating predictions, calculating the difference between predictions and expected outputs, and updating the model’s parameters using an optimization algorithm. This process is repeated over multiple batches and epochs.
2. What are the steps to train a neural network?
The main steps include preparing and preprocessing the dataset, dividing the data into training and evaluation sets, selecting a neural network architecture, initializing the model, choosing a loss function and optimizer, training the model, monitoring validation performance, and evaluating the final model on unseen data.
3. How long does it take to train a neural network?
The training time can range from seconds or minutes for small models and datasets to hours, days, or longer for large deep learning models. Training time depends on factors such as dataset size, model complexity, number of epochs, batch size, hardware, and optimization settings.
4. What data is needed to train a neural network?
The required data depends on the task. Supervised learning generally requires input examples paired with target labels, while unsupervised approaches can work with unlabeled data. The dataset should contain enough representative examples for the model to learn useful patterns and generalize to new inputs.
5. How do you improve the accuracy of a neural network?
Accuracy can potentially be improved through better data preprocessing, additional or higher-quality training data, appropriate feature scaling, architecture adjustments, hyperparameter tuning, regularization, suitable optimizers, learning-rate adjustments, and techniques such as data augmentation. The appropriate approach depends on the model and the problem being solved.